

Metadata & Link Preview API.
Extract a page's title, description, Open Graph and Twitter card tags, Schema.org data, logo and favicon as JSON, without scraping the whole page.


- 500 free credits every month
- No card to start
- Failed requests cost nothing
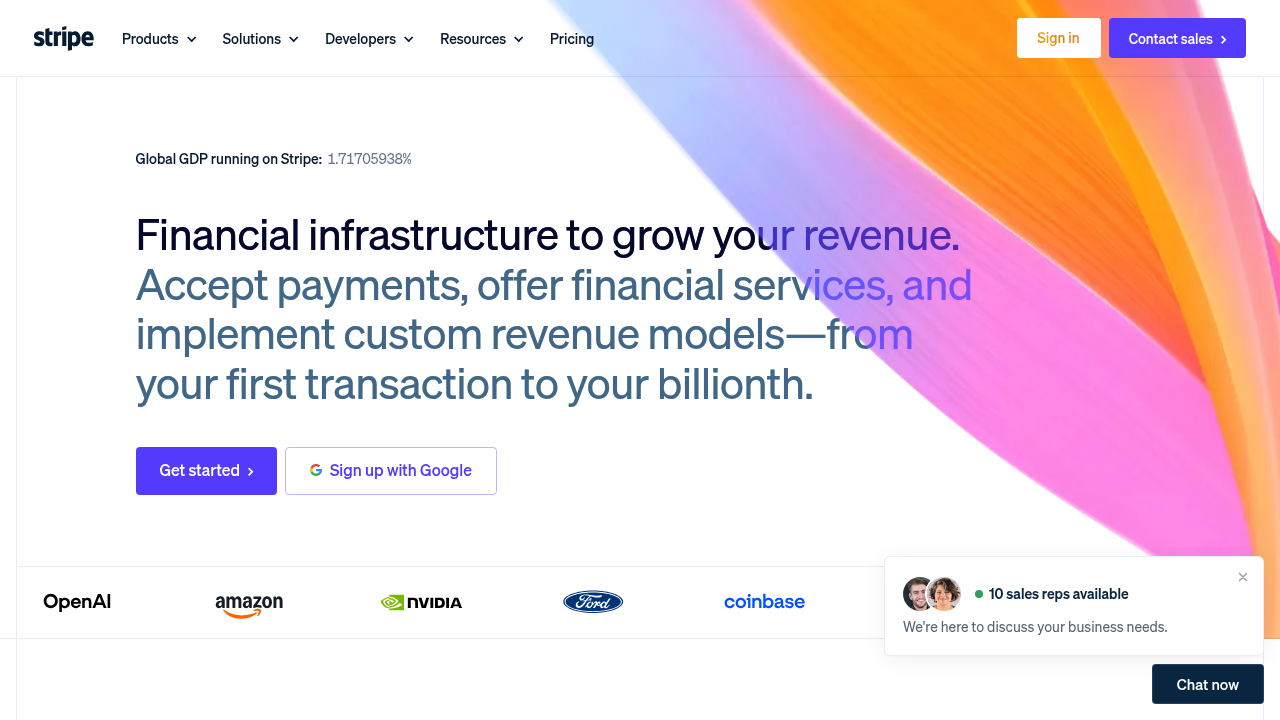
POST /metascraping
{
  "url": "stripe.com"
}


What parsing metadata yourself actually takes.
Reading a title tag takes one line of code. Getting reliable metadata from every site, including ones that render in the browser or block bots, takes a lot more.
| Problem | In-house |  With Geekflare |
|---|---|---|
| JavaScript-rendered tags | Run a headless browser for sites that set their meta tags with JavaScript. | renderJS on by default |
| Every tag format | Parse Open Graph, Twitter cards and plain meta tags, and decide which to trust. | og, twitter and metaTags |
| Structured data | Find the JSON-LD blocks in the page and cope with malformed ones. | schemaOrg as JSON |
| Logos and favicons | Resolve relative icon paths across link tags and manifests. | logo and favicon URLs |
| Blocked sites | Buy proxies for sites that block data-center traffic. | proxyCountry: "de" |
| Mobile versions | Emulate a phone for sites that serve different tags on mobile. | device: "mobile" |
Get the preview each country sees.
Sites often localize titles, descriptions and preview images by country. Add a country code and the request goes through a proxy there, so you get the metadata local visitors get.
proxyCountryroutes a request through any of 194 countries- Check localized titles, descriptions and preview images
- Adds 4 credits only on requests that use a proxy
- 0
- Countries
- Country
- Level of geo-targeting
- Opt-in
- Only when you need
What youn can do with the Meta Scraping API.
Rich previews for every link
Turn any URL your users paste into a preview card with a title, description, image and favicon, in chat apps, CMSs and link-in-bio tools.
- Open Graph and Twitter card tags
- Preview image and favicon URLs
- One request per link
POST /metascraping
{
  "url": "https://stripe.com"
}Your first metadata request, in a few lines.
# pip install geekflare-api
from geekflare_api.client import GeekflareClient
from geekflare_api.models import MetaScrapeDto

with GeekflareClient(api_key="<api-key>") as client:
    result = client.meta_scrape(
        MetaScrapeDto(
            url="https://example.com"
        )
    )
print(result)One API. Every stack.
The same key works from an agent, a workflow builder, an SDK or your own service. Pick the lane you already live in.
MCP server
One remote endpoint exposes Geekflare's tools to any MCP client. Your agent discovers them itself: no glue code, no per-tool wiring.
 Claude
 Cursor
 Codexany MCP client
LLM & agent pipelines
LLM-ready Markdown straight into a retrieval pipeline, with the boilerplate stripped so you spend context on content, not navigation.
Workflow builders
Run any endpoint as a step in a visual scenario. Useful when the person who needs the data does not write code.
SDKs & REST
First-party typed SDKs for Python and Node. Everything else talks plain REST, from any language.
 PythonNode.jsPostman
2 credits a page. Here is what that buys.
Credits are shared with every other Geekflare API. Failed requests cost nothing.
Growth covers up to ~50,000 pages a month (100K credits), about $1.38 per 1,000 pages. Or $58/mo billed yearly.
- 500 credits / month
- 1 team member
- 7 days log retention
- 1 request per second
- 10K credits / month
- 3 team members
- 30 days log retention
- 5 requests per second
- 100K credits / month
- 5 team members
- 30 days log retention
- 10 requests per second
- 1M credits / month
- 25 team members
- 90 days log retention
- 25 requests per second
What developers say after switching.
“I explored multiple tools for accessing metadata, but none were pleasing until I found Geekflare. It’s cost-effective and has good proxy support. The playground is good, and their support team responds quickly.”
“Easy-to-use REST API to extract website metadata for SEO analysis. Highly recommend for social tags and schema markup.”
“Its been couple of years we are using Geekflare API, we like its stable production ready performance and cost-effectiveness of accessing multiple APIs through a single plan.”
 Jitendra RauloDirector, Aarav Infotech
Before you integrate metadata.
Everything else is in the endpoint docs, and our support team replies to every email.
Open the endpoint docsproxyCountry adds 4 credits. Failed requests cost nothing.renderJS: false for faster requests on static pages.format: "markdown" to get the metadata as Markdown, which is handy as compact context for AI models. JSON is the default.proxyCountry routes the request through a proxy in that country, which often gets past these blocks.250 pages a month, free.
The free tier renews every month and needs no card. Get your first page's metadata in a single call.